A/B Test
Open In A New Tab
Ron Kohavi, Lukas Vermeer and Jakub Linowski predict that opening product pages in a new tab helps shoppers compare. Yet no high-powered experiment has confirmed it: attempts at Metro and Obs only showed directionally positive signals. Here’s what 8 past experiments found so far:
QuestionDoes opening links in a new tab allow more product comparisons, which in turn increases purchase rate and basket size?
defaults
from
 Ron Kohavi
Ex-Airbnb, Microsoft & Amazon
 Jakub Linowski
Founder of GoodUI


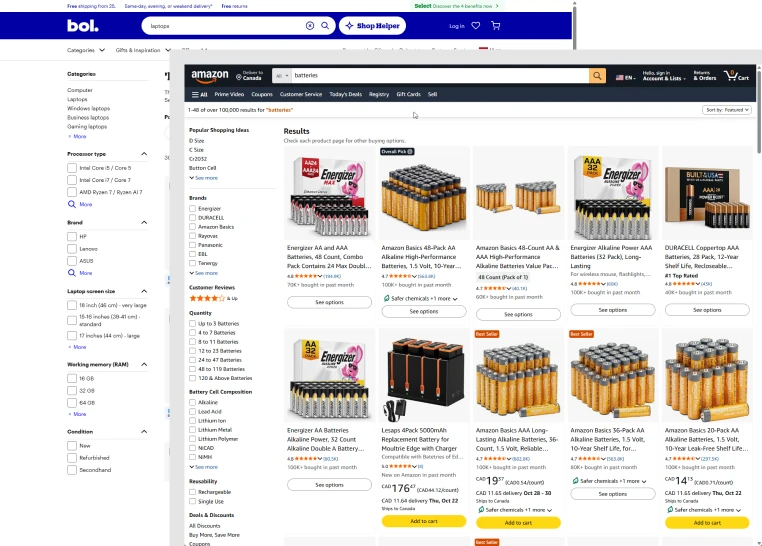
Bol.com & Amazon
are opening product/listing links in the same window
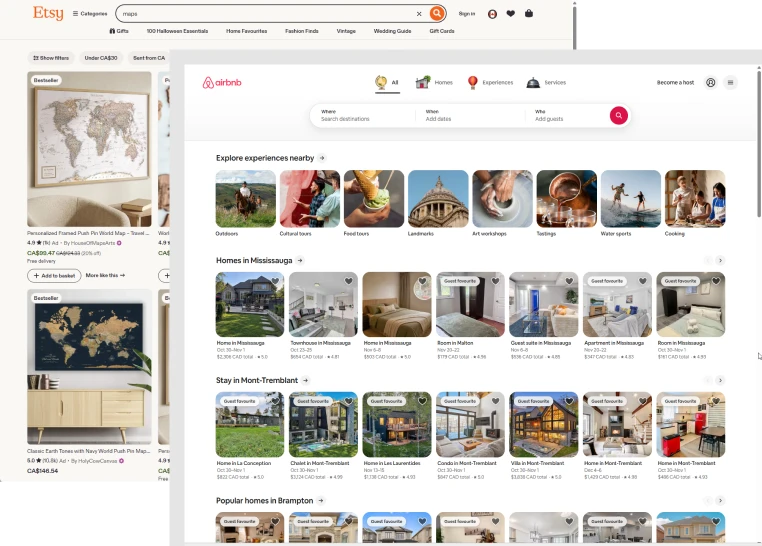
Etsy & Airbnb
are opening product/listing links in a new tab
Experiment Design
Choose the structure of your experiment.
Treatment Variables
Tick what each variant changes, or save it for a follow-up experiment. Some choices are backed by past tests; others are still hunches. Impact
| Treatment variableInclude in | Future | ||||
|---|---|---|---|---|---|
|
|
|||||
|
Evidence
↑ 2 of 3 tests (Tests 666, 644, 645)
|
|||||
|
the browser default
|
|||||
|
|
|||||
|
|
|||||
|
Exploratory
sets the expectation
|
|||||
|
|
|||||
|
Exploratory
shows what's already open
|
|||||
|
|
|||||
|
|
|||||
|
|
|||||
|
Evidence
↑ 1 of 2 tests (Pattern #92)
|
|||||
|
|
|||||
|
|
|||||
|
Exploratory
keeps the comparison going
|
|||||
|
|
|||||
|
|
|||||
|
|
|||||
|
Exploratory
run as its own variant
|
|||||
|
|
Targeting / Triggering
Refine where and when the test fires, beyond the page types chosen above in order to increase power (and shorten the testing duration). NoiseVelocity
Variance Reduction
Cancel out noise you can predict, to get more power from the same traffic. NoiseVelocity
Metrics & Ship Requirements
Mark each metric as Primary, Secondary, or Guardrail, then set the requirement it must meet to ship. ImpactIteration
| Metric | Primary | Secondary | Guardrail | Superiority | Non-Inferiority | Binary | Continuous |
|---|---|---|---|---|---|---|---|
| % | |||||||
| % | |||||||
| % | |||||||
| % | |||||||
| % | |||||||
| % | |||||||
| % | |||||||
| % | |||||||
| % | |||||||
| % |
Power, Sample & Duration
The effect you want to detect and how long you'll run to reach the power for it. Noise
Enter a baseline rate and MDE to estimate the sample size.
Meta-Analysis
Combine your experiment with that of others to reach a decision faster or increase power. NoiseVelocity
Start Rules
When can the experiment start?
Stop Criteria
When to end the experiment. Each early stop trades some power for a shorter run. Quality
Segments
Which subgroups should we track and break the results down by, to see if the effect differs across them? Iteration
| Segment | Your Bet | Exclude | Measure |
|---|---|---|---|
|
Likely stronger
|
|||
|
Likely weaker: tab switching is harder
|
|||
|
|
|||
|
Likely stronger: tiles link to products
|
|||
|
Likely stronger: tiles link to products
|
|||
|
Likely weaker: links go to categories
|
|||
|
|
|||
|
|
|||
|
|
|||
|
|
|||
|
|
|||
|
Likely stronger: more to compare
|
|||
|
Likely stronger
|
|||
|
|
|||
|
Likely weaker: the page already compares
|
|||
|
Likely stronger
|
|||
|
Likely stronger: nothing to compare with yet
|
|||
|
|
|||
|
|
|||
|
|
|||
|
|
|||
|
Likely stronger: similar products need comparing
|
Iteration Rules
What next experiments to run once the results come in.
| Outcome | Re-run with: Higher intensity | Higher power | Elsewhere | Something different | Invert | Move on |
|---|---|---|---|---|---|---|
| IF Stat sig primary A clear, significant win. | ||||||
| IF Stat sig primary Flat secondary A win on primary, no effect on secondary. | ||||||
| IF Flat primary Stat sig secondary No effect on primary, a win on secondary. | ||||||
| IF Flat primary Flat secondary No significant effect on either. | ||||||
| IF Stat sig neg primary A clear, significant loss. |
Export to Experimentation Tools
Pick a destination — copy a plain-text spec, or a JSON config for your platform.
Now Run This Experiment
- Unlock the evidence behind each variable
- All evidence-backed defaults revealed
- Design review
- Power and metrics review
- Targeting and scope review
- Full implementation and QA
- Test run and monitoring
- Result review and write-up
A GoodUI subscription unlocks the A/B test evidence behind every variable in this design, plus all of its evidence-backed defaults, so each choice is backed by data from similar experiments.
Beyond the review, we teach you or your team the reasoning behind it, so the next test is one you can design and judge yourselves. Pick whichever lessons you're interested in:
Hand it off. We design, implement, and QA the test, run and monitor it for you, then review the results and deliver a write-up — you get the outcome without the build effort.
- Metric alignment and setup Define the primary metric, guardrails, target audience, tracking events, attribution window and launch criteria so the test measures the decision you actually need to make.
- Power calc Estimate baseline conversion, minimum detectable effect, sample size and runtime before launch, with a clear read on whether the test is likely to be decisive or exploratory.
- Prototype-quality code Build the variation to prototype quality in your testing tool or front-end stack, with responsive states, analytics hooks, QA notes and handoff-friendly implementation details.
- Analysis Read the result with significance, confidence intervals, guardrail checks and segment caveats, then translate the stats into a practical ship, stop or iterate recommendation.
- Post-test and iteration recommendations Turn the result into next moves: what to keep, what to change, what to retest and which follow-up experiments are most worth running next.
- Discussions Use async or live discussion time to clarify assumptions before launch, review tradeoffs during the run and unpack ambiguous outcomes after the test closes.

- Design
- Power & MDE
- Metrics & guardrails
- Targeting & scope
- Iteration suggestions